
A temporary redirect where a permanent one belongs. Found by Redirect checker →redirect loop
The URL redirects back to itself and never settles. Found by Redirect checker →
Internal linking and crawl depth audit
Orphan pages, deep click depth, dead ends, pages linked only from navigation, nofollow-only inlinks and an internal link score compared with the site median.
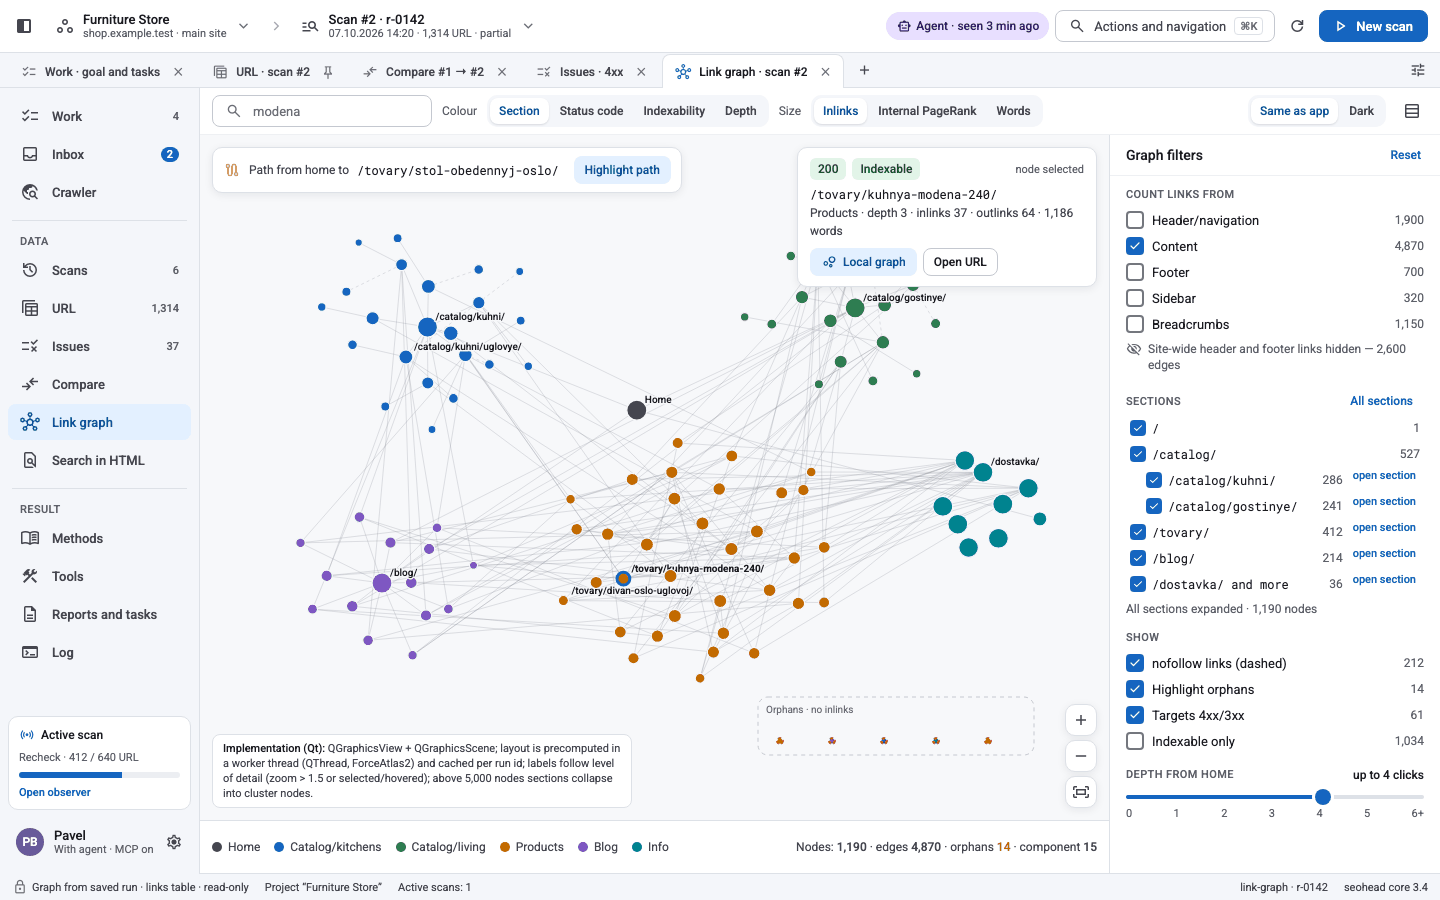
Internal linking and crawl depth audit
Structure
Inlinks and outlinks per page, discovery path and click depth from the start URL.
Anchors
Generic anchors such as 'read more' and duplicate links on the same page.
Three steps, one saved scan
Crawl the site from one start URL
crawl-site follows same-host links from the start URL, respects robots.txt by default and stores every link in one SQLite file.
Map the link graph
Each page gets its inlinks, outlinks, click depth from the start URL and the position of each link: navigation, footer, or body copy.
Flag orphans, dead ends and weak links
Checks report pages no link reaches, dead ends, pages linked only from boilerplate or nofollow, and anchors such as 'here'.
Checks in this feature
| Check | What it means | Severity | Evidence |
|---|---|---|---|
ORPHAN_PAGE | The page has no internal inlinks in the crawl | Important | Inlink count for the URL |
DEEP_CLICK_DEPTH | The page is more clicks from the start URL than the configured floor | Important | Click depth and the shortest path from the start URL |
NO_INTERNAL_OUTLINKS | Dead-end page with no internal links going out | Important | Page URL and outlink count |
INLINK_BOILERPLATE_ONLY | The page is linked only from navigation, header, sidebar or footer, never from body content | Important | Inlink positions by template area |
ONLY_NOFOLLOW_INLINKS | Every internal link to the page is nofollow | Important | Inlink list with rel attributes |
LOW_LINK_SCORE | Internal link score is far below the site median | Tip | Page score against the site median |
GENERIC_ANCHOR_TEXT | Anchor text such as 'here', 'read more' or 'click here' does not describe the destination | Tip | Source page and anchor text |
One command
seohead crawl-site --url https://example.com --max-urls 1000 --scan-out ./scans/links.sqliteInstall first: installation guide. Every command also runs as an MCP tool for AI agents.
From the check registry
ORPHAN_PAGEDEEP_CLICK_DEPTHNO_INTERNAL_OUTLINKSINLINK_BOILERPLATE_ONLYLOW_LINK_SCOREGENERIC_ANCHOR_TEXT