
A temporary redirect where a permanent one belongs.
Found by Redirect checker →
The URL redirects back to itself and never settles.
Found by Redirect checker →
Duplicate and thin content checker
Exact duplicates by hash, near-duplicates, thin pages, low text ratio, boilerplate and placeholder text across a crawl.
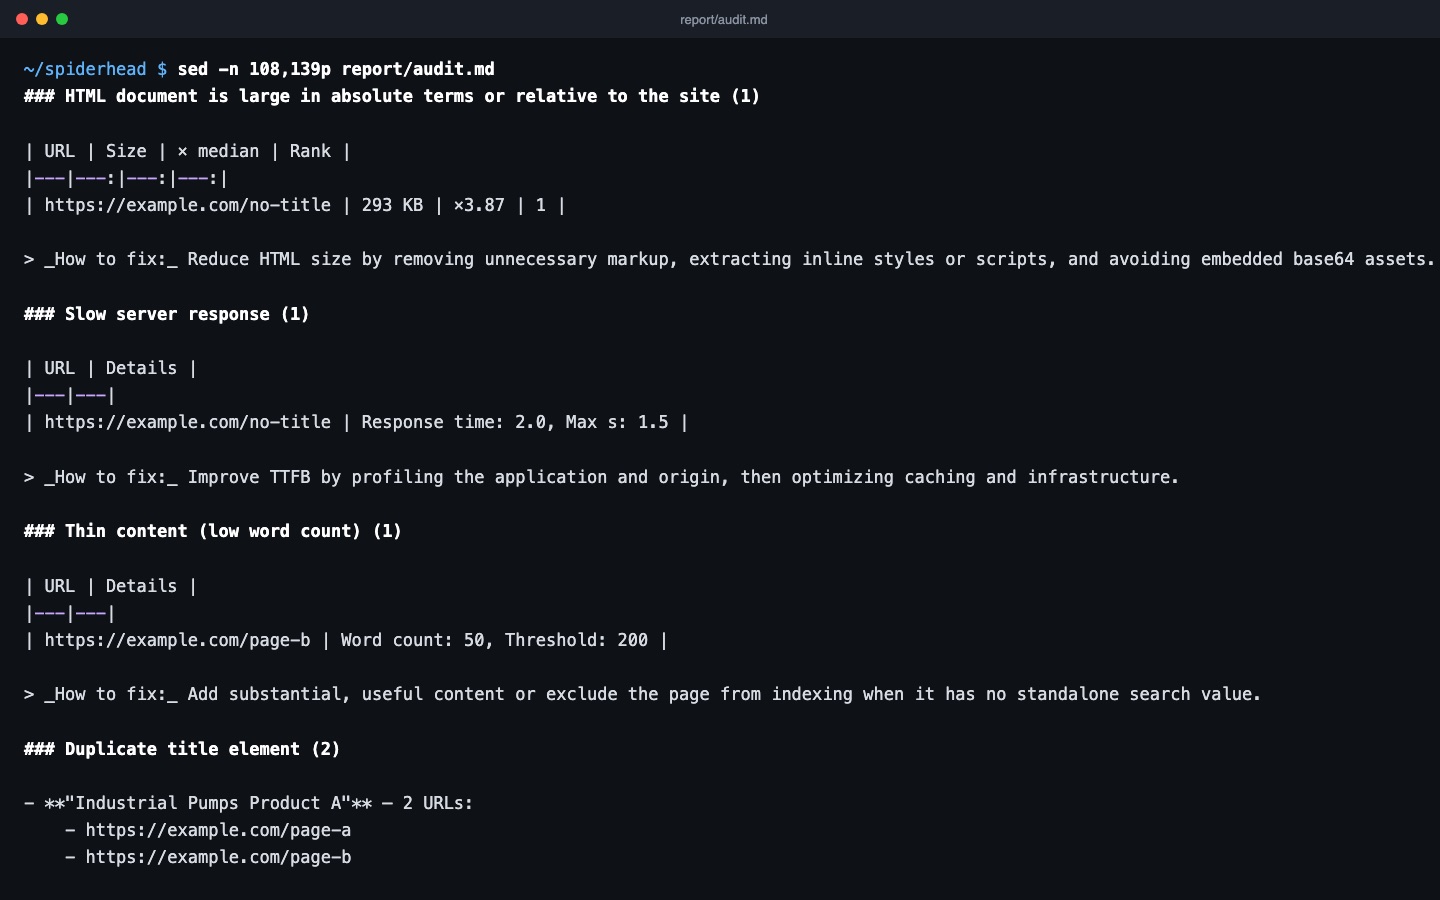
Duplicate and thin content checker
Content analysis
Near-duplicates, boilerplate, semantic inputs and similarity over retained page bodies.
Duplicate and thin content checker
Readability
Flesch score and long sentences as optional content checks.
Three steps, one saved scan
Crawl the site into a scan
Run a crawl. It saves a native SQLite scan that keeps each page's extracted text for offline analysis.
Compare every page body
Exact copies are found by content hash. Near-duplicates are found with simhash and LSH, so pages are not compared pair by pair.
Read the groups and fix them
Each finding lists the pages in its group. Consolidate with a canonical tag or rewrite the pages so each one serves its own search intent.
Checks in this feature
| Check | What it means | Severity | Evidence |
|---|---|---|---|
DUPLICATE_BY_HASH | The page body is identical to another page's body | Important | Hash group with the URLs that share it |
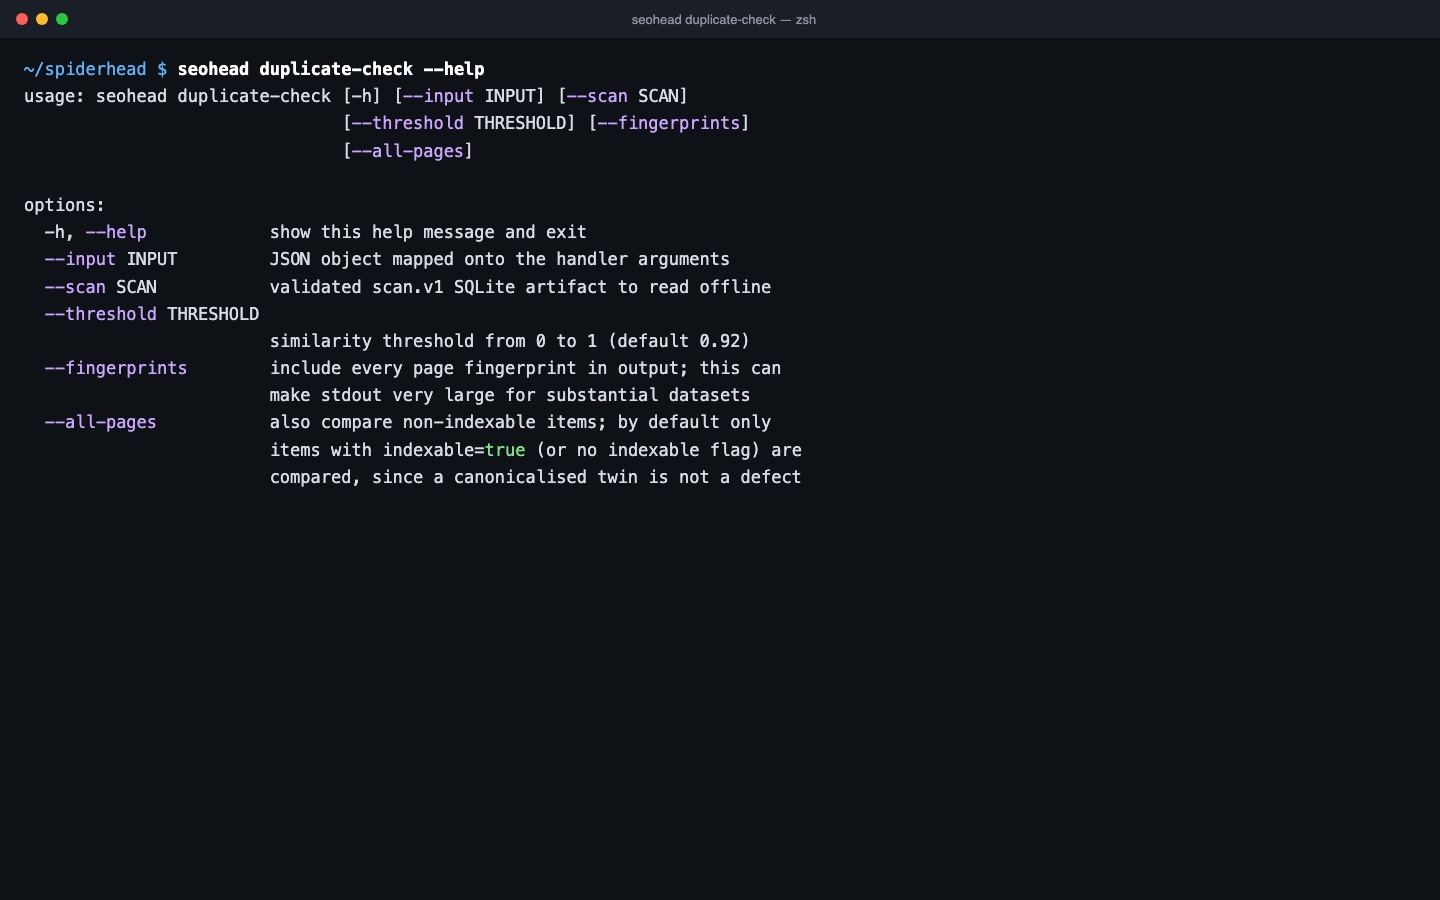
NEAR_DUPLICATE | The page text is almost identical to another page's text, above the similarity threshold (default 0.92) | Important | Cluster of similar URLs |
THIN_CONTENT | The page has too few words to stand on its own in search | Important | Word count for the page |
LOW_TEXT_RATIO | Visible text is a small share of the HTML, so markup outweighs content | Tip | Text-to-HTML ratio for the page |
LOREM_IPSUM_PLACEHOLDER | Lorem Ipsum placeholder text is in the page's main content area | Important | Matched placeholder passage |
READABILITY_DIFFICULT | Text has a low Flesch reading-ease score. This is an optional content check | Tip | Flesch score for the page |
One command
seohead duplicate-check --scan ./scans/audit.sqliteInstall first: installation guide. Every command also runs as an MCP tool for AI agents.
From the check registry
DUPLICATE_BY_HASHNEAR_DUPLICATETHIN_CONTENTLOW_TEXT_RATIOLOREM_IPSUM_PLACEHOLDER