
A temporary redirect where a permanent one belongs.
Found by Redirect checker →
The URL redirects back to itself and never settles.
Found by Redirect checker →
Free local SEO crawler
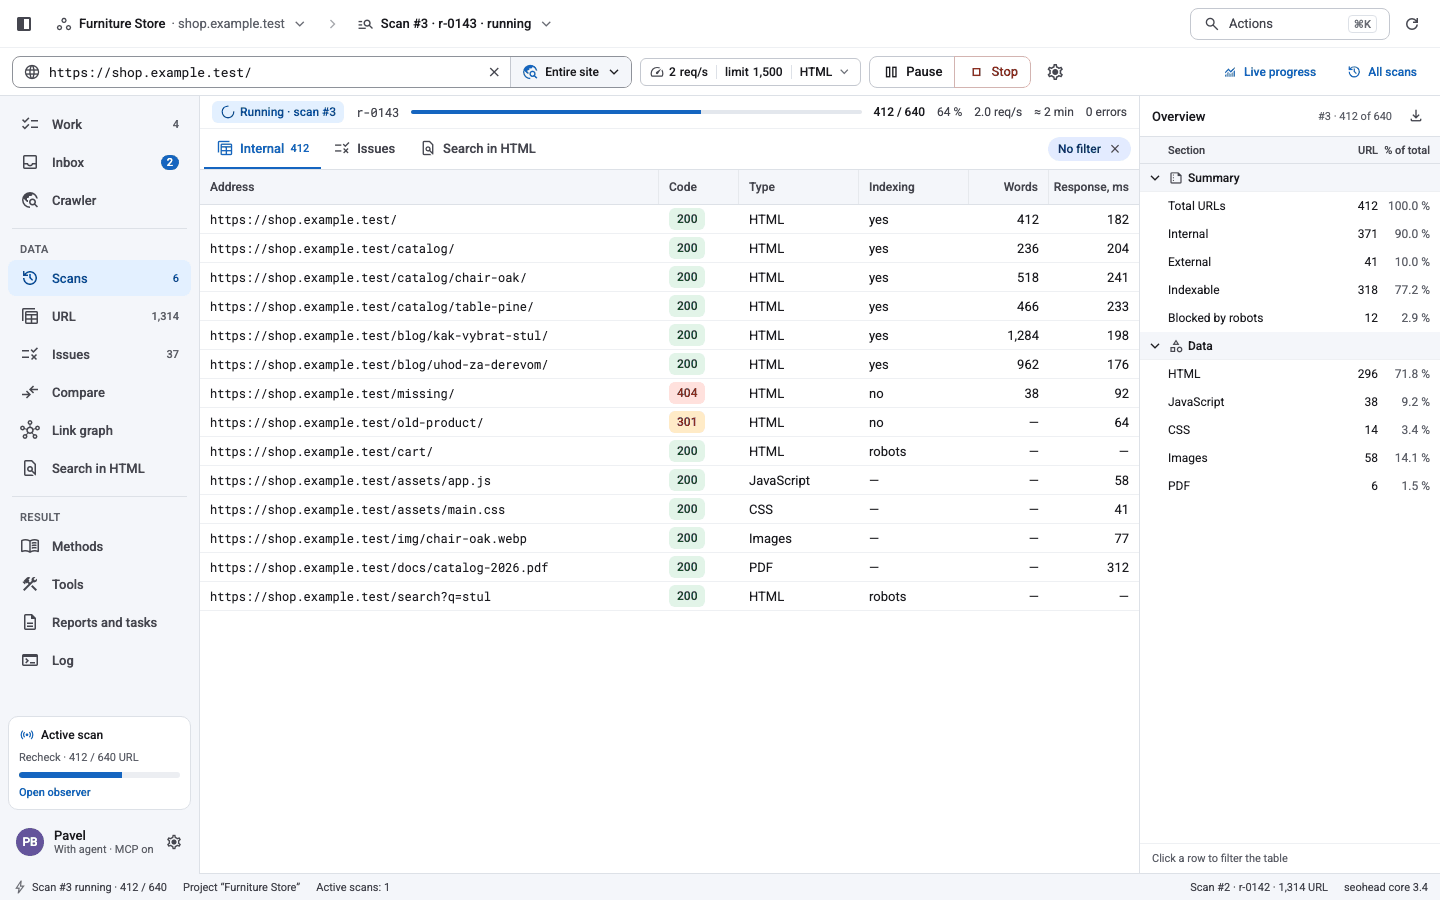
SpiderHead crawls a site from a start URL on your own machine, follows links on the same host, respects robots.txt and audits the result with the same checks it uses for Screaming Frog exports.
Free local SEO crawler
Crawl without a project
In the desktop app, enter a URL and press Start; save the result as a project later. In the terminal, crawl-site writes one native SQLite scan you can reopen, export and reanalyse.
- Same host when following links
- robots.txt respected
- Free and local: no hosted account
Free local SEO crawler
Checks that cannot run say so
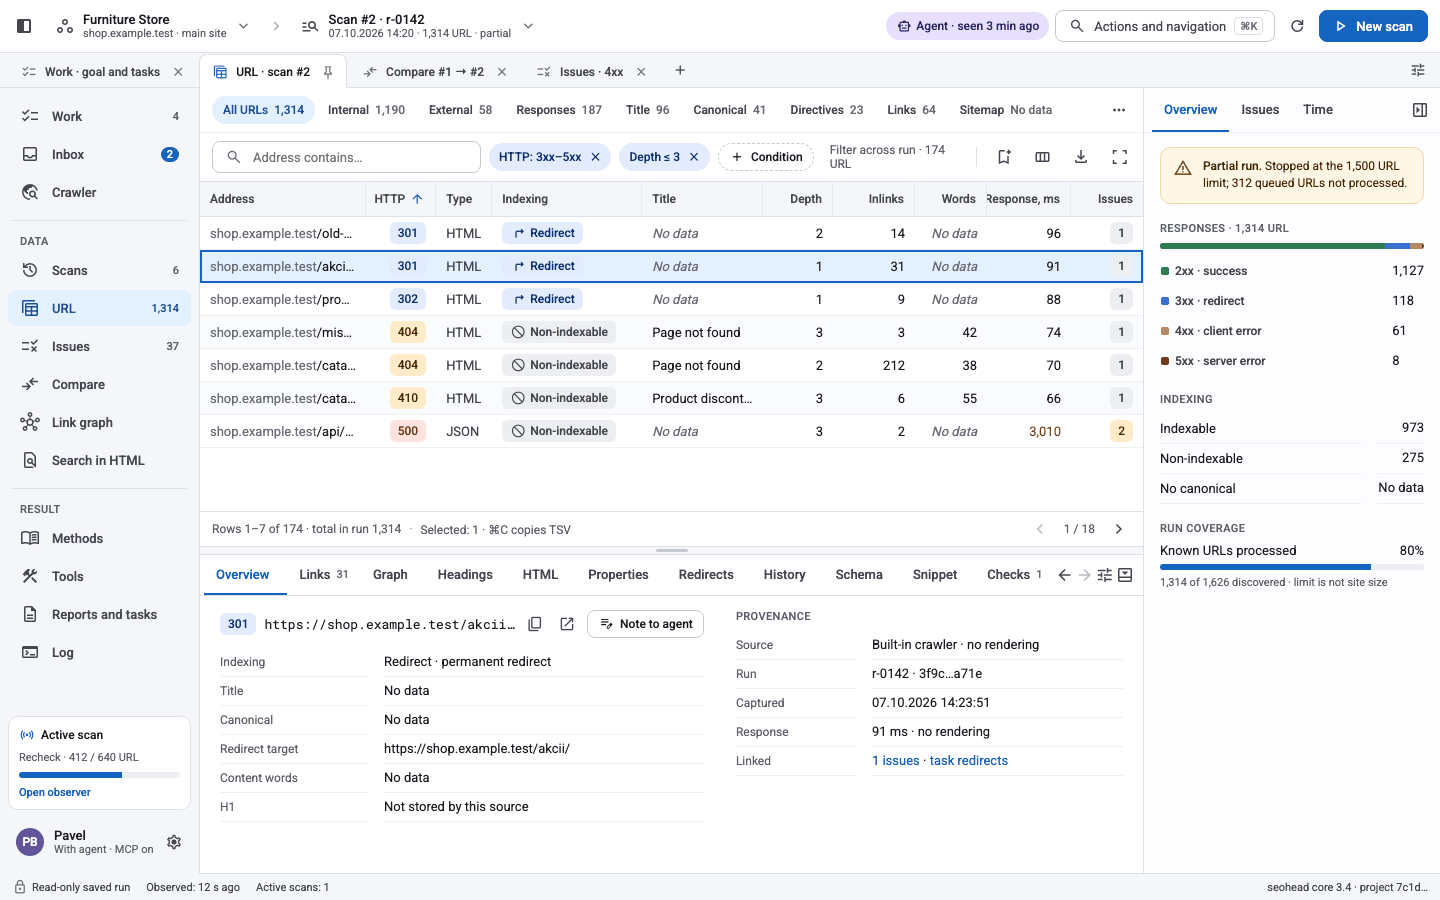
A native crawl cannot produce every kind of evidence. Checks that need what it did not collect come back skipped with a reason, never as a false clean.
- Finding, ran without findings, skipped or failed
- Partial crawls withhold link-graph claims
Three steps, one saved scan
Start from one URL
Enter a start URL in the desktop app, or run crawl-site in the terminal. It follows links on the same host and writes one native SQLite scan you can reopen.
Stay polite by default
About two requests per second per host, with adaptive delays. You set the URL cap; the default is 200 URLs.
Audit the same evidence
The crawl is checked with the same registry as Screaming Frog exports. A check that needs data a native crawl cannot collect is marked skipped with a reason, never clean.
Checks in this feature
| Check | What it means | Severity | Evidence |
|---|---|---|---|
BROKEN_PAGE_4XX | The crawled page returns a 4xx response | Critical | URL and response status |
SERVER_ERROR_5XX | The crawled page returns a 5xx response | Critical | URL and response status |
NO_RESPONSE | No response: timeout, DNS or connection failure | Critical | URL and failure reason |
BROKEN_INTERNAL_LINK | An internal link points to a 4xx URL | Critical | Source page and link position |
REDIRECT_LOOP | The redirect chain returns to a URL it already visited | Critical | Loop path |
REDIRECT_CHAIN | Two or more redirect hops before the final URL | Important | Every hop with status |
BLOCKED_BY_ROBOTS | robots.txt blocks the URL, so the crawl did not fetch it | Important | URL and matching robots.txt rule |
One command
seohead crawl-site --url https://example.com --max-urls 500 --scan-out ./scans/audit.sqliteInstall first: installation guide. Every command also runs as an MCP tool for AI agents.
From the check registry
BROKEN_PAGE_4XXSERVER_ERROR_5XXNO_RESPONSEBLOCKED_BY_ROBOTS