
A temporary redirect where a permanent one belongs.
Found by Redirect checker →
The URL redirects back to itself and never settles.
Found by Redirect checker →
Resume an interrupted crawl
Crawls are resumable. A scan is a retained SQLite artifact with provenance, so a stopped crawl continues from where it stopped instead of starting again.
Resume an interrupted crawl
Retained scans
Every scan is kept: inspect, export, snapshot, pin, prune, requeue, diff bodies and reanalyse offline without contacting the site again.
- scan-reanalyze reparses retained HTML
- Snapshots and pins for baselines
Recovery
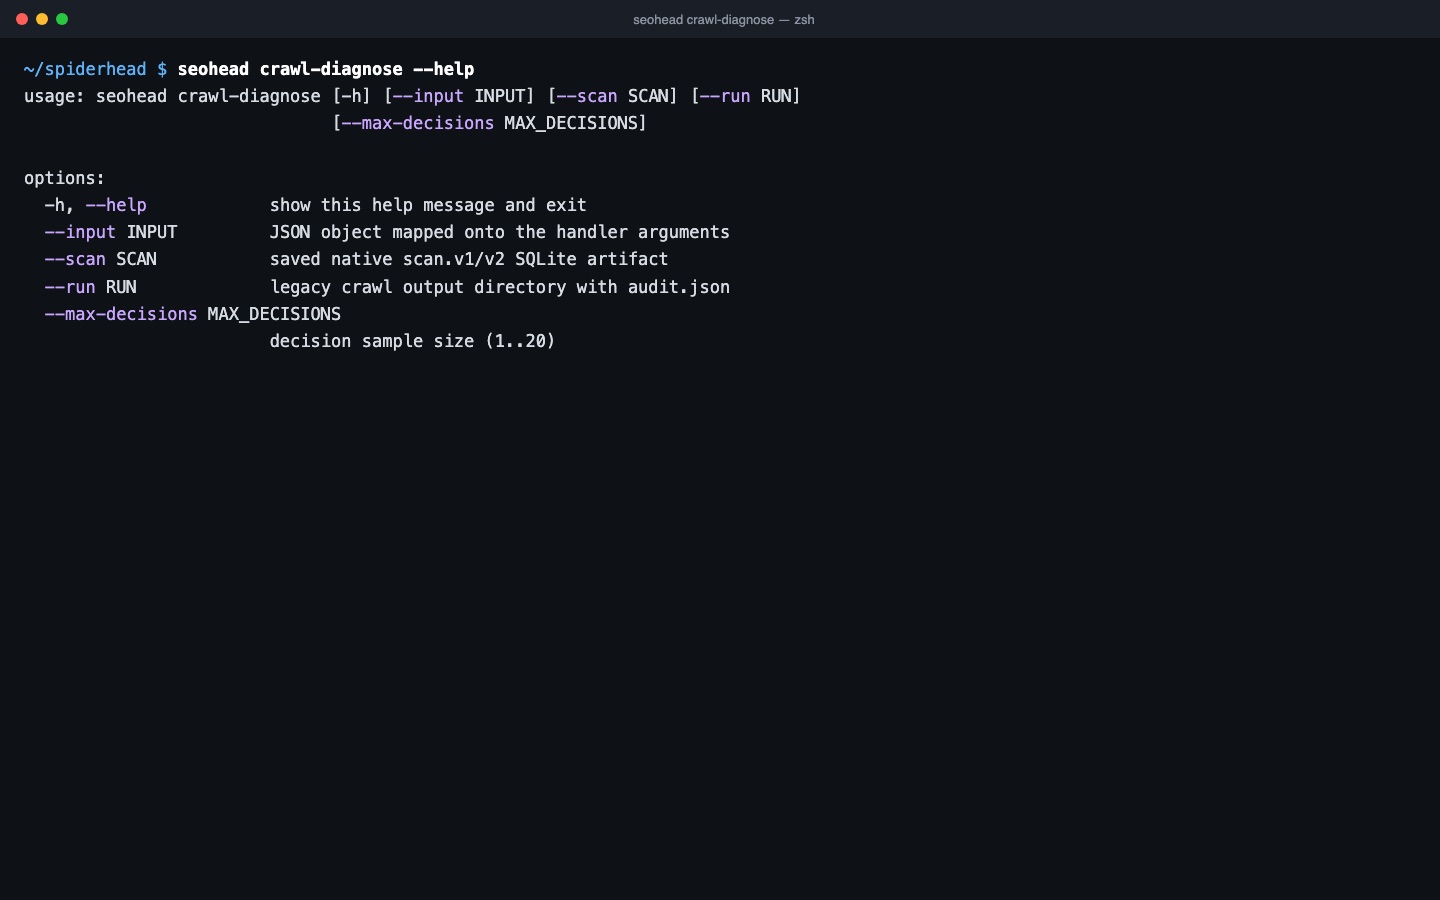
Interrupted runs are recorded and can be resumed; crawl-diagnose explains what stopped a crawl.
Three steps, one saved scan
The scan file is the checkpoint
A SQLite scan keeps the queue, the evidence and the full settings in one file. They are written in the same transaction, so a stop does not split them.
Resume from the file alone
Run seohead crawl-site --resume with the scan path. The start URL and settings are read from the file, so the crawl continues under the same rules.
Diagnose what stopped it
crawl-diagnose reads the scan offline. It shows the queue, robots, scope and budget state, the content types and the recorded failures, with no network request.
Checks in this feature
| Check | What it means | Severity | Evidence |
|---|---|---|---|
NO_RESPONSE | The URL timed out, failed DNS or refused the connection. A stopped origin often shows up here. | Critical | URL and failure type in the scan |
SERVER_ERROR_5XX | The page returns a 5xx status, for example when the origin stops responding under load. | Critical | URL and status code |
BROKEN_PAGE_4XX | The page returns a 4xx status, so it is broken for users and crawlers. | Critical | URL and status code |
BLOCKED_BY_ROBOTS | robots.txt blocks the URL. Confirm the block is intended before resuming. | Important | URL and the robots.txt rule |
One command
seohead crawl-diagnose --scan ./scans/audit.sqliteInstall first: installation guide. Every command also runs as an MCP tool for AI agents.